AI Creation · 2026
MemeSonic (Meme-to-Audio)
Cross-modal synthesis of contextual audio from meme semantics; proposes FusionMOE, trimodal alignment
Case Study
Demo
Generate voiceovers from memes
& Emotional synergy among the three modalities
1 Generation
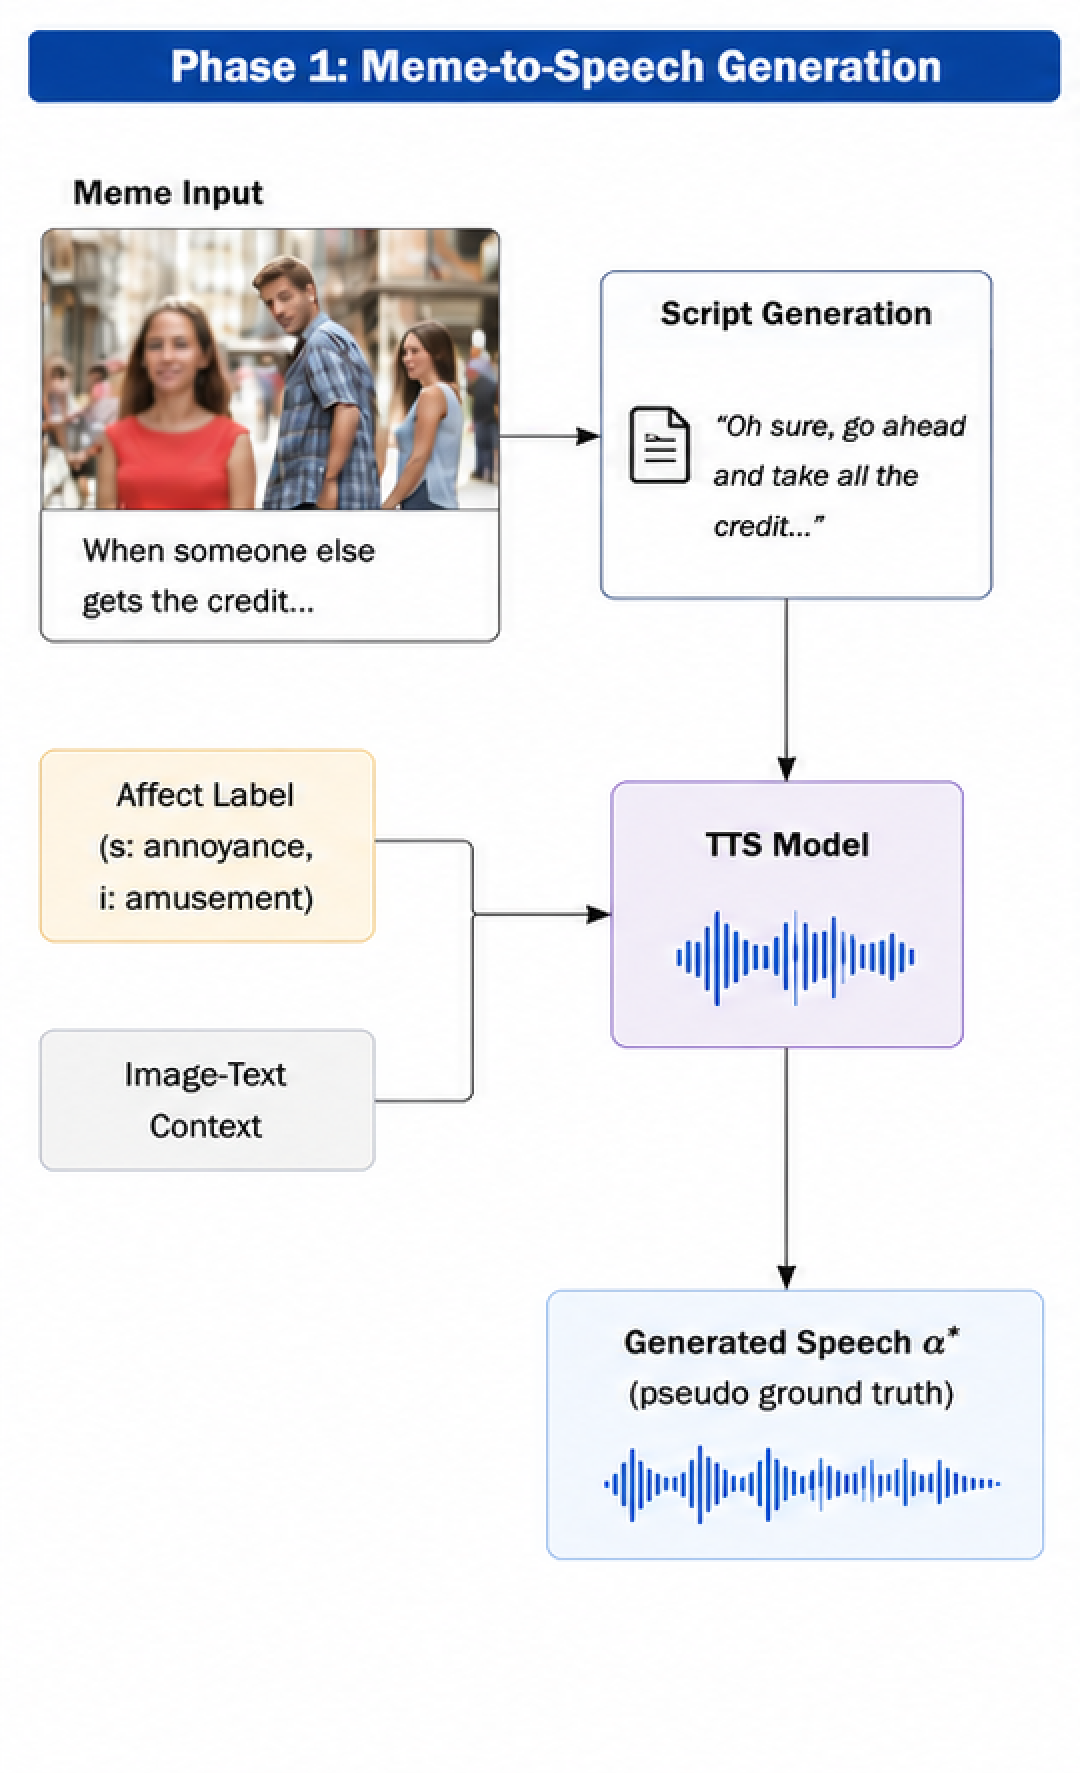
Developed a pioneering cross-modal system that synthesizes contextually relevant audio based on the deep semantic reasoning of internet memes.
The "Humor Gap" Challenge: Solved the limitation where current LLMs/Vision models struggle to decode the complex, non-linear humorous logic (irony, dark humor) that arises from the "semantic friction" between text and image.
Advanced Reasoning: Leveraged cutting-edge Multimodal Alignment (e.g., SigLIP/BLIP-2) and Foundation Models (e.g., LLaVA/Gemini Vision) to interpret hidden humorous metaphors.
PM Impact - Capability for Virality: Lowered the content creation barrier by enabling models to autonomously identify "meme-able" visual patterns and pair them with emotive, context-aware audio, fostering a richer ecosystem for shareable content.
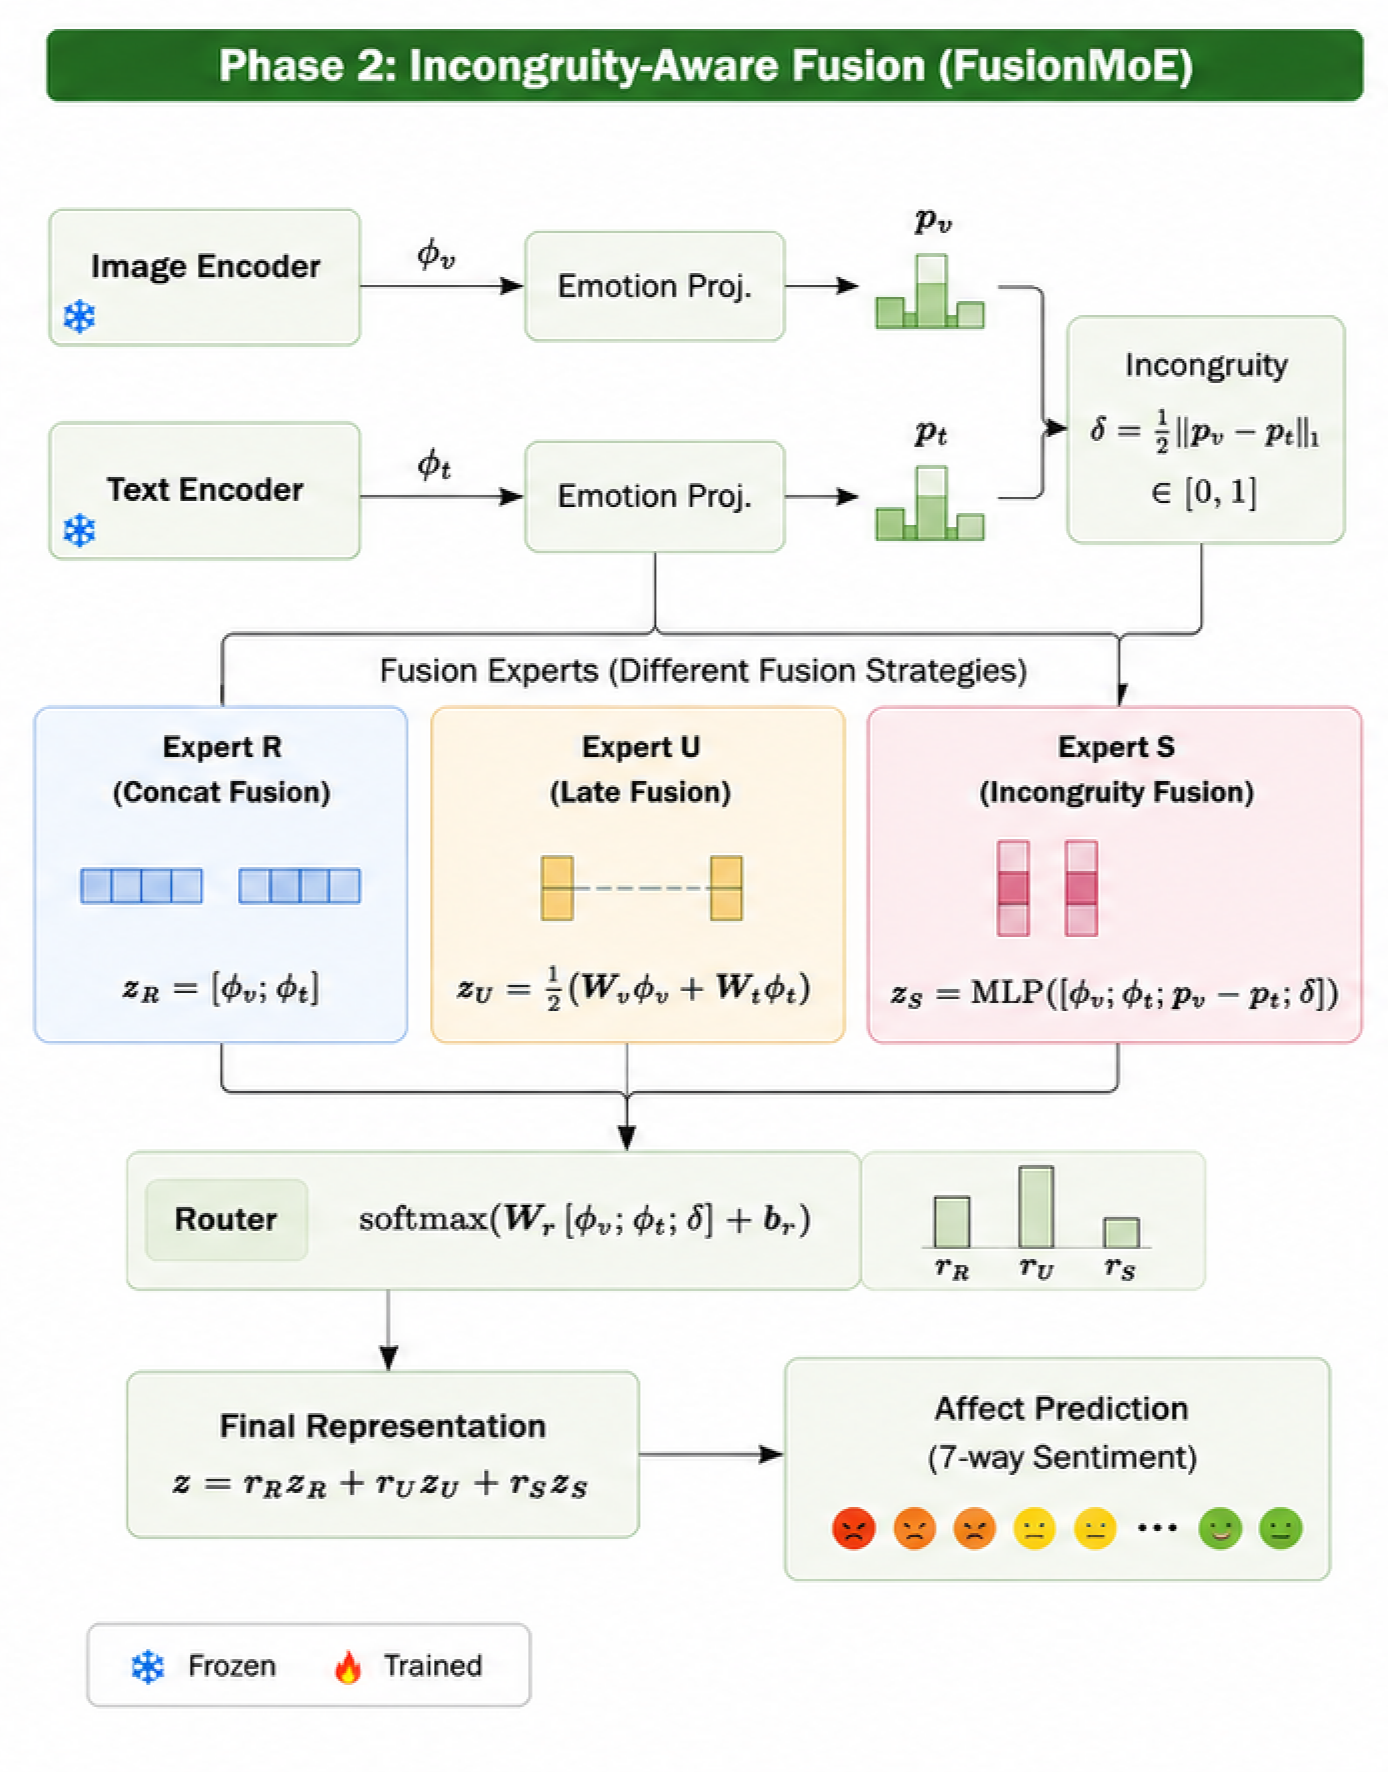
2 Fusion
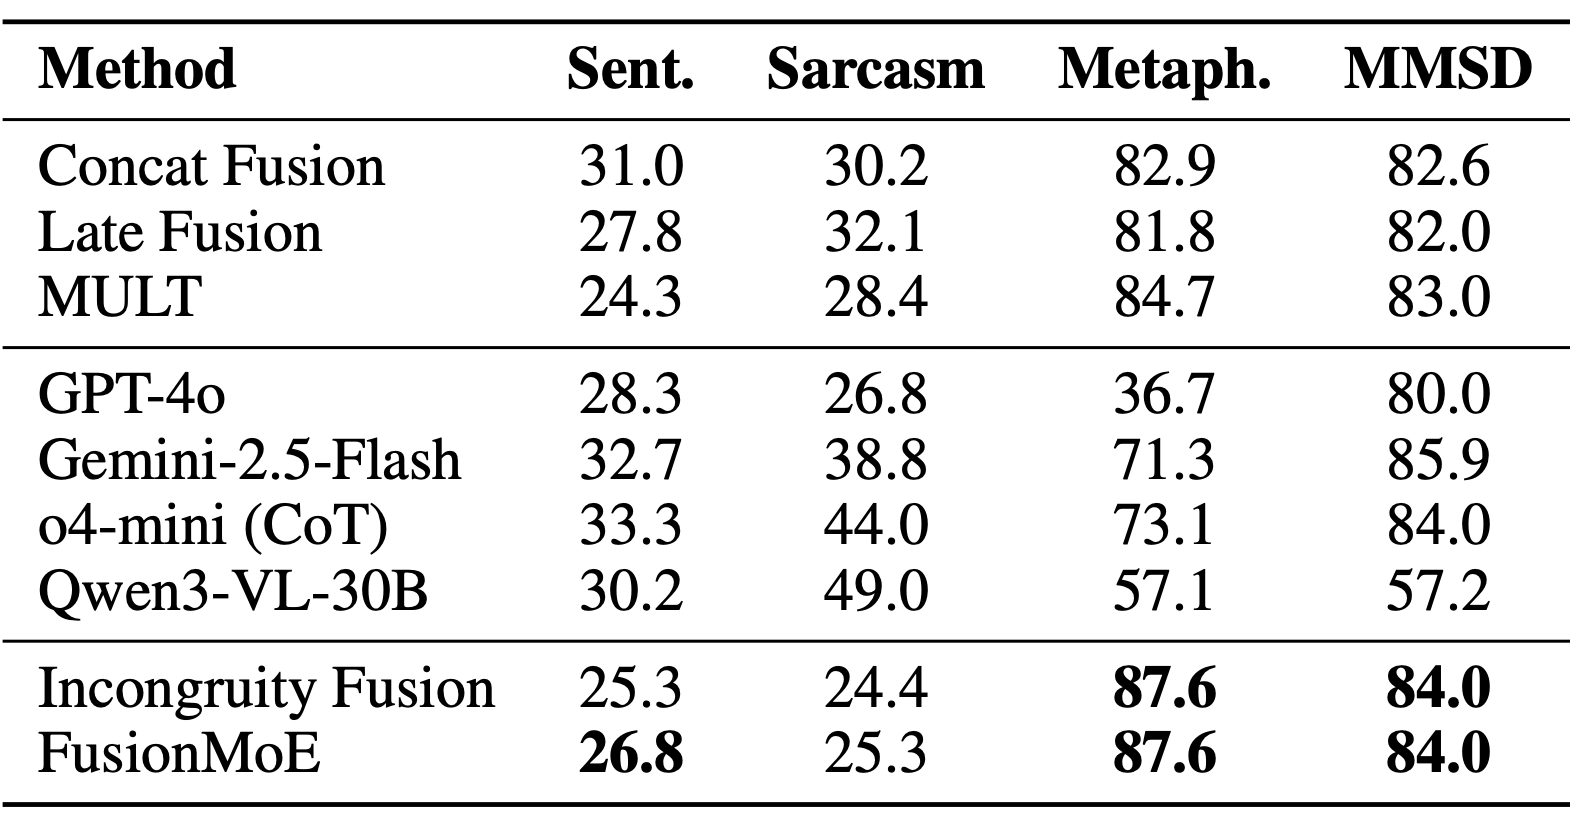
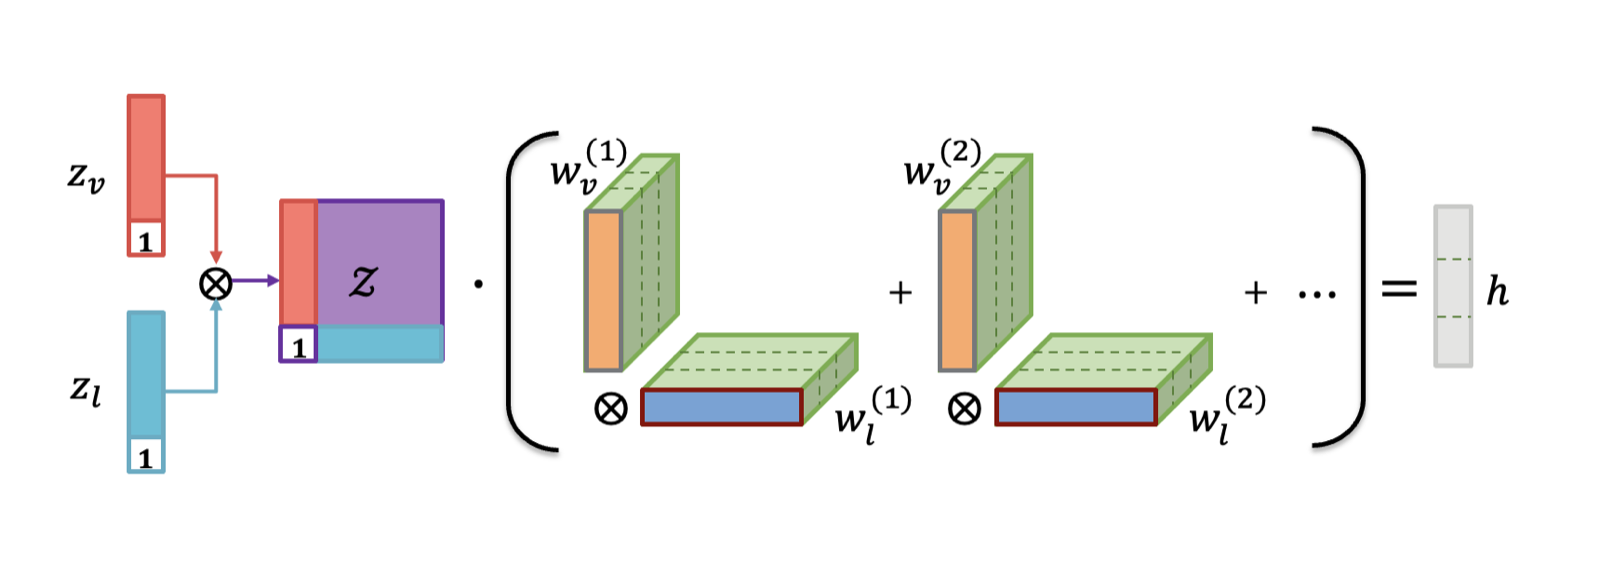
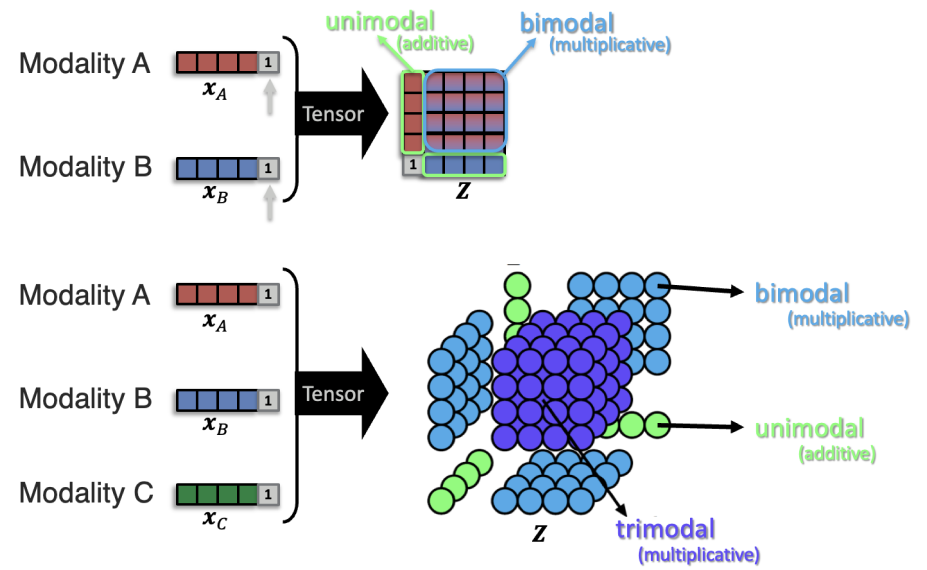
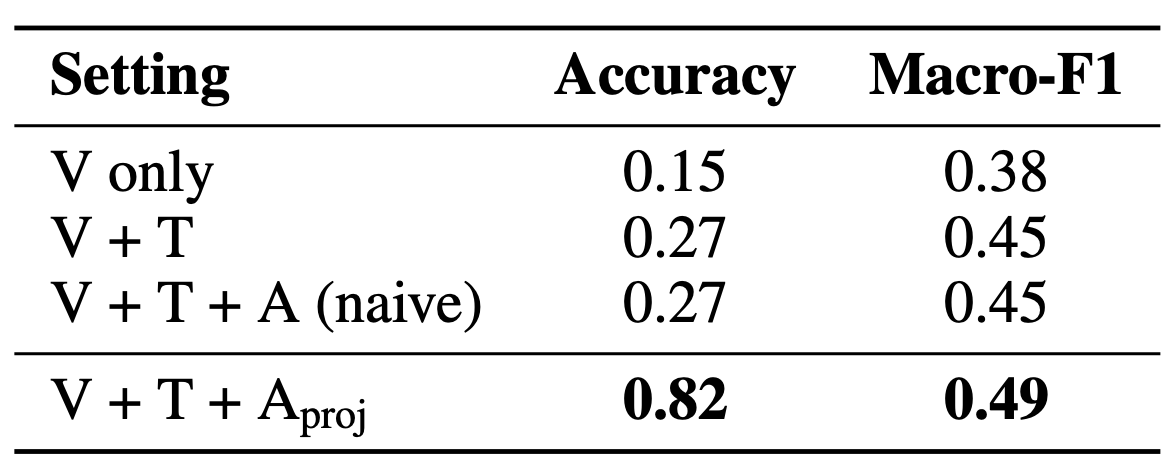
propose FusionMOE
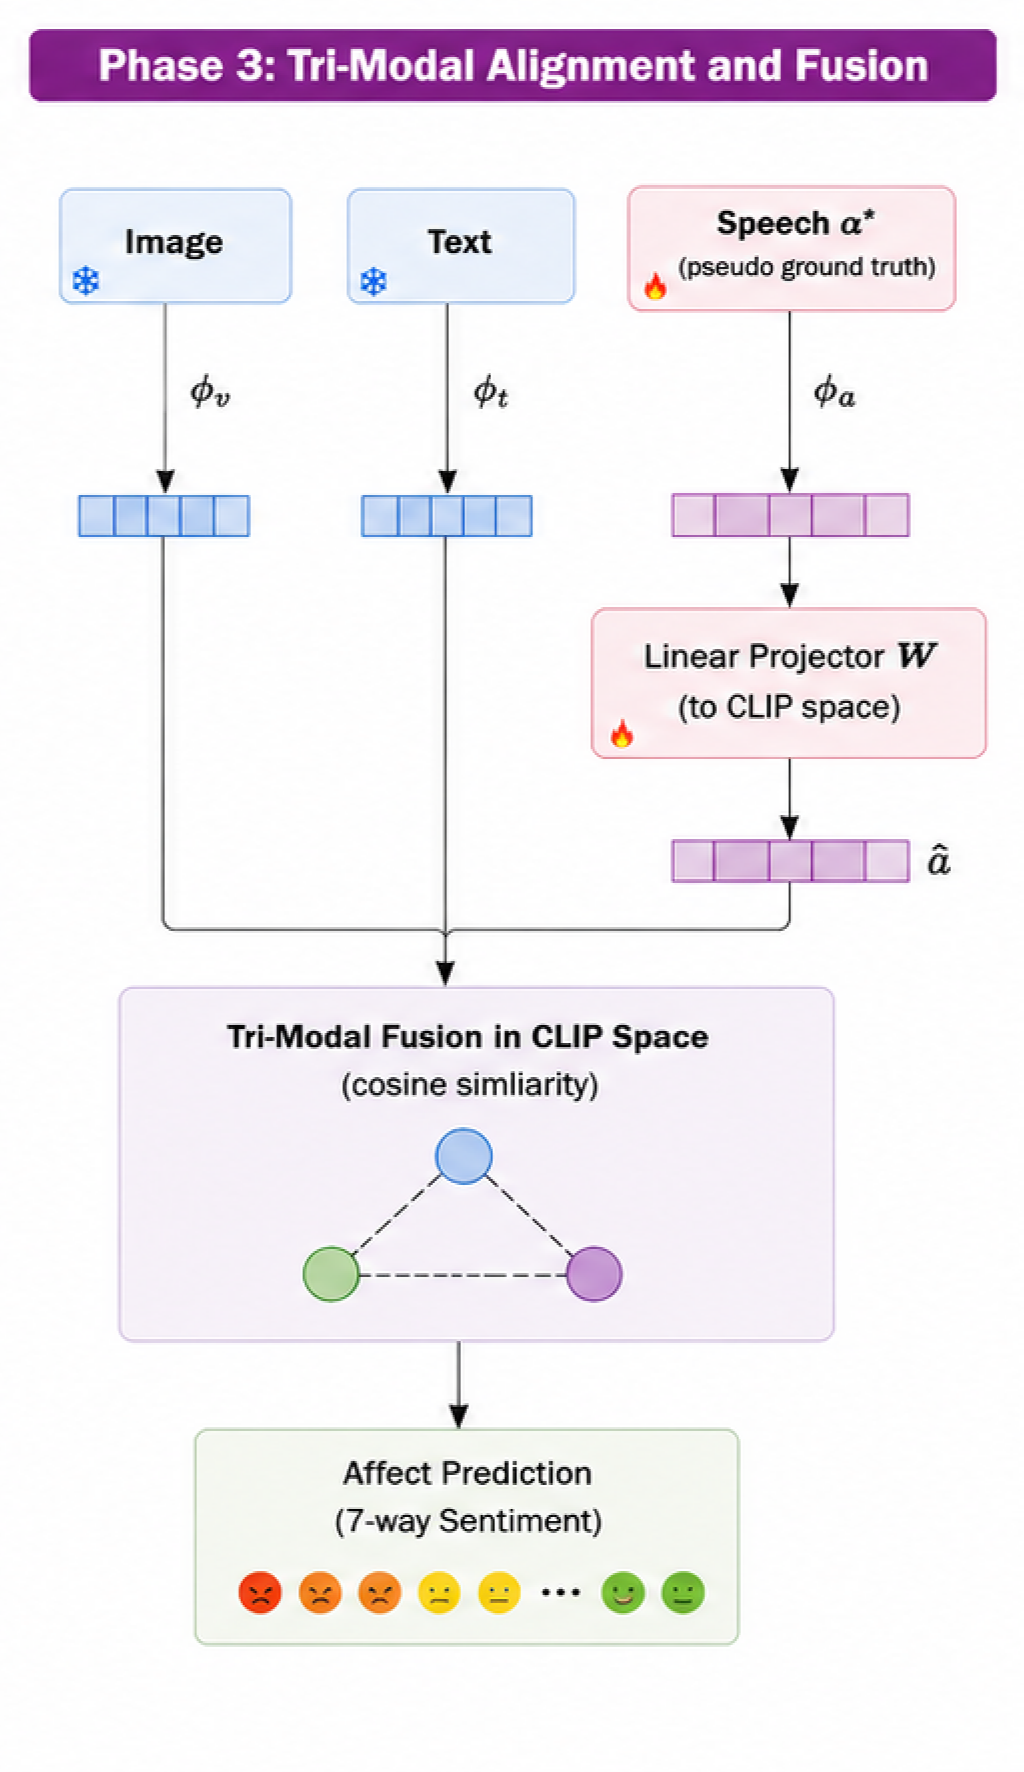
3 Trimodal Alignment
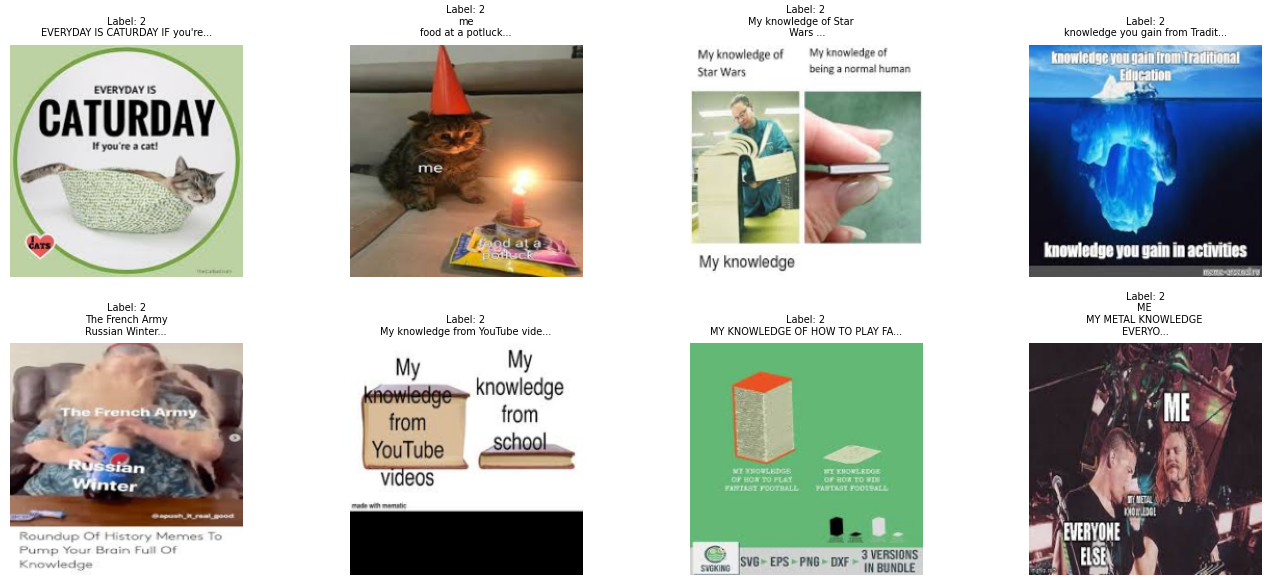
Data Sample
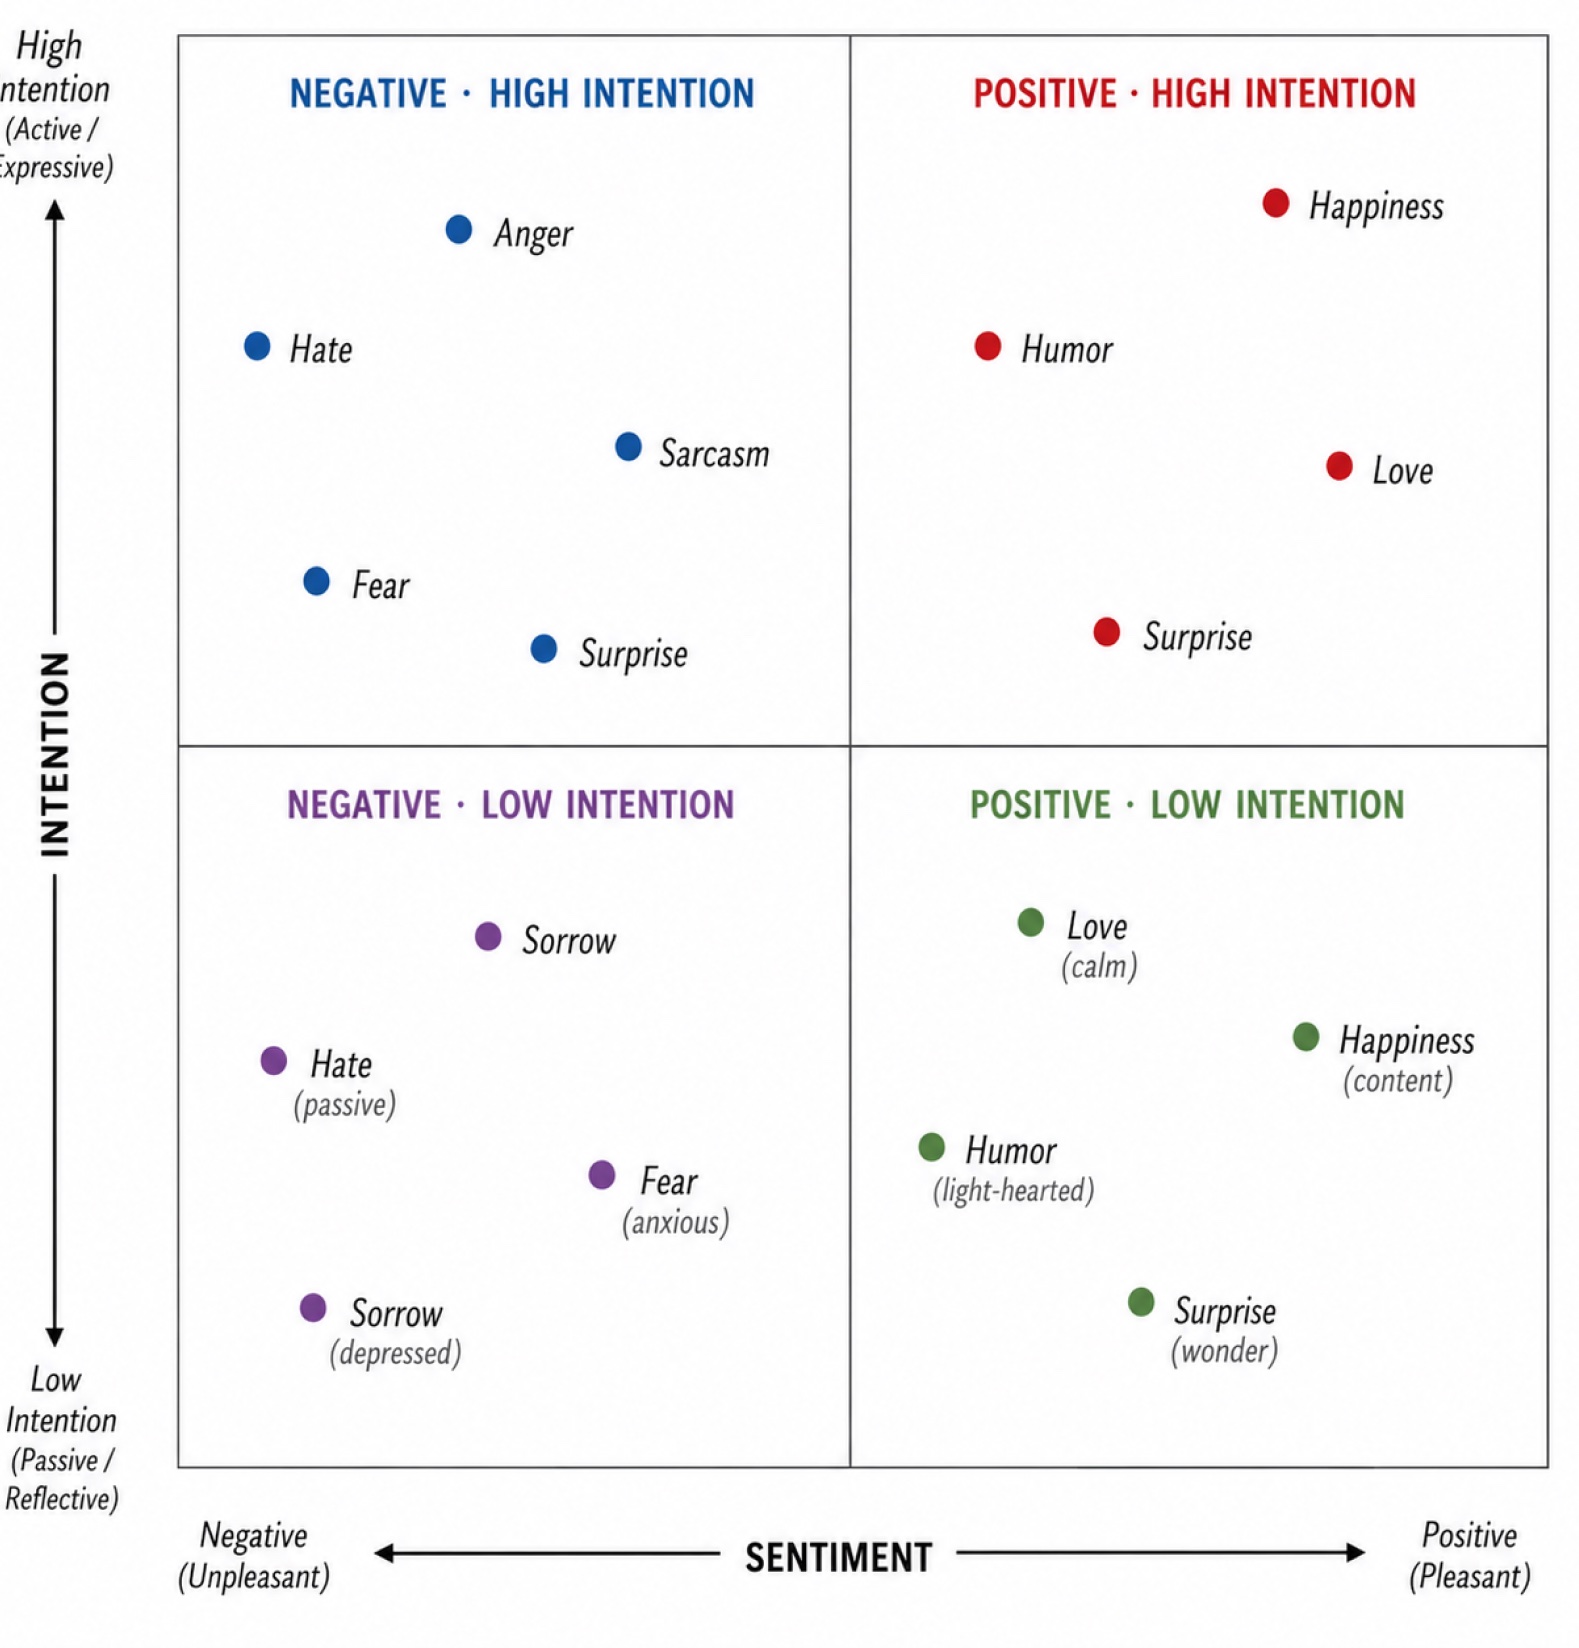
intention: Interactive, Expressive, Entertaining, Offensive